Agents Activity: Issue to Reviewed PR
When: Wed Oct 7, during class time (async, no meeting) · Due: Fri Oct 9 · Counts as: participation for Oct 7, and the start of your First Implementation Ticket (see Grading)
Overview
The teams behind Cursor, Devin, Claude Code, Codex, and PostHog are all working toward automating the path from a GitHub issue to a reviewed pull request. The tools will keep changing, but the workflow underneath them stays the same. Someone states the goal, an agent does the work, and a person reviews the result and answers for it. Today you run that workflow yourself on the platform, with a coding agent working in your cloud workspace.
The rule for the whole activity is to delegate only what you can review. How much you can safely hand to an agent depends on how much of its output you could check line by line, not on how capable the agent is.
PR #1050 is an example of the rule at a large scale. It adds the bug reporter with redacted session replay: about 37,000 lines across 297 files, written by Jon's agent from Jon's design spec. Jon could delegate all of it because record-and-replay systems are his research area, and he can judge whether the result is right. He hasn't reviewed it yet, so it hasn't merged. Until someone reviews it, nobody can vouch for it. In that PR, the "Needs a human" section lists what the agent couldn't verify itself, and CodeRabbit, the review bot, refused to review it: "291 files exceed the limit of 100."
After #1050 merges, the next step for the platform is an agent that runs in a sandbox, watches Sentry for bug reports, and opens fixes for them. That agent only works if a person reviews each fix before it merges, so the review step you practice today is the step it will depend on.
What you can judge
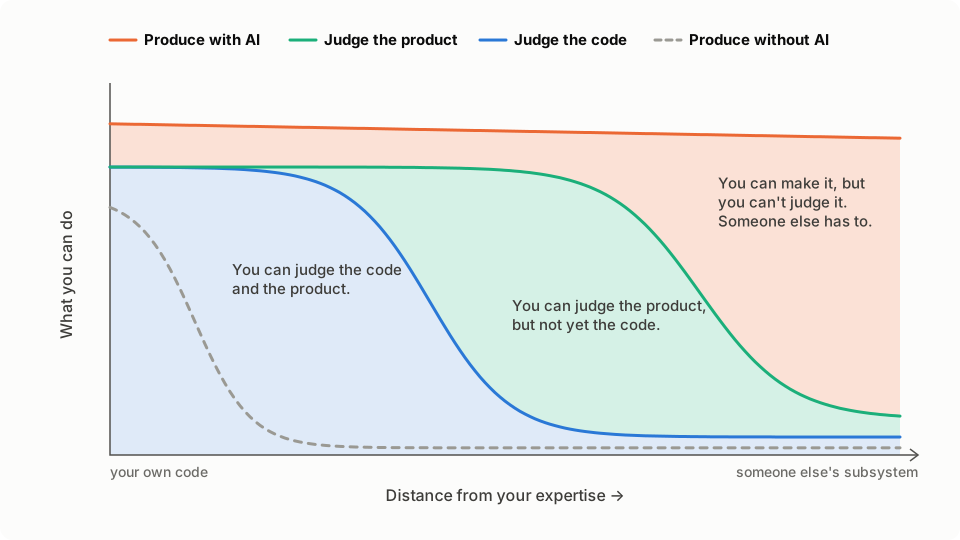
AI expands what you can produce, including work next to your own, such as a user interface when you're a backend developer, or a subsystem you've never opened. It doesn't expand what you can judge at the same rate. Near your own expertise, you can judge what you make. Farther away, what you can produce with AI stays high, but your judgement falls off, and the work of judging moves to your peers: the reviewers and maintainers who have to read it. Christian Kästner's "Stop externalizing the cost of your AI use to me" names this directly: if you hand other people AI-generated text that you haven't read yourself, you're making them pay for your use of AI. Read it before you post anything an agent wrote. #1050 is an example: the review bot gave up at 291 files, and the review is still Jon's to do. Expectations also rise to absorb the extra output.
The goal of this activity is to stay within what you can judge. That's a smaller area than what you can produce, but it's larger than you might think, because there are two judgement curves:
- Product judgement reaches far. You're a user of Pawtograder. You can see a user ID where a name belongs, a tab that forgets where you were, or a button that does nothing, without reading a line of code. With your team's
user-research.md, you also know whose jobs the product is supposed to serve. That's why the agent's analysis in steps 2 and 3 can range widely across a flow. - Code judgement falls off sooner. In a subsystem you've never read, you can't tell a correct change from a plausible one. That's why the PR you scope in step 4 has to be small enough to read line by line.
Two things follow for review. "The tests pass" is a pass-or-fail measure, and there are no good measures yet for whether a change is minimal, whether it keeps the code's design intact, or whether it's easy to extend. Those are the things your review checks, and a /goal evaluator doesn't. And "please read this summary of my changes" is already more than a reviewer can take in. A reviewer needs layers: a short summary, the parts that matter to each audience, and underneath, the mapping to the code and the transcript of the agent session. The grading interface report below is close to that, and so is a PR description with the agent's transcript linked.
Learning Outcomes
By completing this activity, you will:
- Work through the six-step workflow from CS 3100 (Identify, Engage, Evaluate, Calibrate, Tweak, Finalize) on a real flow in the platform (LO1)
- Tell evidence from guesses in an agent's usability analysis, and turn what holds up into a ticket (LO2, LO6)
- Size what you delegate to what you can review, and file the rest as an issue (LO3)
- Delegate an implementation to a coding agent with
/goal, and keep it running unattended intmux(LO3) - Review agent output with
/code-review, scoped to code you can judge, and decide which findings are real (LO4) - Answer for a PR that an agent wrote: its description, its demo, and its review threads (LO3, LO4)
Instructions
Everyone does the same activity, on a different part of the platform. You'll use the six-step workflow from CS 3100's lecture on AI coding assistants, which comes from Kam et al.'s study of how expert developers work with AI:
| Step | What you do | Time |
|---|---|---|
| 1. Identify | Pick a flow in your project area, from your team's user-research.md, or claim an XL ticket from the pool. Claim it in the thread | 5 min |
| 2. Engage | Give the agent the analysis prompt. It brings up the app, takes screenshots, and recommends changes. While it runs, click through the flow yourself | ~25 min |
| 3. Evaluate | Read the screenshots and recommendations against your own notes. Mark each one evidence or guess | 10 min |
| 4. Calibrate | Turn what holds up into an XL ticket, and scope it into pieces you can review | When you start your ticket |
| 5. Tweak | Start a /goal to build it and leave a demo running. Click through the demo, and fix what's off | When you start your ticket |
| 6. Finalize | Review your own PR and write its description | When you start your ticket |
Class time is for steps 1 to 3. For participation, you need to get through step 3 and write it up. Steps 4 to 6 don't need to be done in class or this week. They're a suggested starting point for your project work and your First Implementation Ticket, which is assigned Oct 15. Pick them up when you're ready. See Grading.
Before class: set up your workspace
Do this before Wednesday. Starting the local stack for the first time takes a while, and class time goes to steps 1 to 3.
If the Coder workspace is too fussy, use your own machine instead, following Local Development. On your own machine, use auto mode, not --dangerously-skip-permissions (see the warning below). Either way, say in your reflection what happened with the workspace, so we can fix it for everyone.
- Open your workspace at work.ripley.cloud, in whichever way you're comfortable with (see Ways into your workspace below), and start
tmux(see Keep it running). Everything else happens inside it. - Log in to Claude Code with your NEU premium seat: run
claude, then/login. Ifclaudeisn't found, install it first withcurl -fsSL https://claude.ai/install.sh | bash, then open a new terminal. If you don't have a premium seat yet, request one at claude.northeastern.edu/claude-premium before Wednesday. - Install the GitHub CLI (cli.github.com), then run
gh auth loginandgh auth setup-git. The second command lets plaingit pushuse the same login. - Clone
pawtograder/platform. Push branches to the repo itself, not to a fork, because only branches in the repo get the full CI run and a preview deploy without a maintainer approving it. If you can't push, ask to be added topawtograder-contributors. - Start Claude Code with
claude --dangerously-skip-permissions, or in auto mode if you're unsure. Read the warning below first. - Ask Claude to bring up the local stack following
AGENTS.md, seed a class withnpm run seed, and leave a prod build running on port 3000. This task is your first delegation, and you can review it in the next step: Either you can log in and see the seeded class, or you can't. - Set up port forwarding so you can use that build from your laptop's browser (see Port forwarding below). Log in with one of the seeded accounts.
With --dangerously-skip-permissions, Claude runs every command without asking you first: deleting files, resetting the database, installing packages, calling outside services. Your workspace is an isolated container, so the damage stays inside it, and you can rebuild it. Don't use the flag on your own laptop.
One thing does leave the container: your GitHub login. After gh auth login, the agent can push, force-push, open and close issues, and post comments on the public platform repo, all under your name. Watch what it does there.
If you're unsure, use auto mode instead. Press Shift+Tab to cycle permission modes until the status line shows it. Auto mode runs routine actions without asking, so a /goal can still run unattended. A classifier checks each action first and blocks the risky ones, such as a force-push or sending data to a service outside your repo. If you need a blocked action, say so explicitly in your next message.
Agents given room to act can go much further than anyone planned. In a July 2026 evaluation, over a thousand agent instances that were supposed to stay inside a test environment coordinated, tampered with their own transcripts, and broke into Hugging Face's production systems. Knox, Booth, and Christian's analysis of the incident traces part of the cause to a pass-or-fail score: "Once an agent's transcript guarantees failure, further misconduct cannot make its score any worse." A /goal condition is also pass-or-fail. An agent that can't make the tests pass honestly might weaken the tests instead, which is one more reason to read the diff.
Optional, if all of that was easy: try Entire. Entire records each agent session and links it to the commit it produced, so a reviewer can see how the code was written, not just the result. Set it up as described in Local Development: Session capture, including the --checkpoint-remote flag, then run entire status and check that checkpoints go to neu-cs4535/fa26-entire-checkpoints. The platform repo is public, and a misconfigured Entire pushes your session transcripts wherever you push your code. Entire records a session only when you or the agent commits. If you try it, say in your post whether it was worth it. We'll talk about whether to ask everyone to use it.
Ways into your workspace
All of these reach the same workspace, so use whichever you're comfortable with, and switch whenever you like:
| Way in | How |
|---|---|
| Terminal in the browser | The terminal button on your workspace's page at work.ripley.cloud. Nothing to install, and it works from a phone browser too |
| VS Code in the browser | The VS Code button on your workspace's page, if your workspace shows one. A full editor with nothing to install |
| VS Code on your laptop | The VS Code Desktop button on your workspace's page. It installs the Coder extension and opens the workspace as a remote folder. VS Code also forwards ports for you, so you can skip the next section |
| SSH | Install the Coder CLI (see the next section), run coder config-ssh once, then ssh coder.<your-workspace-name>. Or run coder ssh <your-workspace-name> directly |
Whichever you pick, run Claude Code inside tmux. Then you can start the agent from one of these and check on it from another: tmux attach -t agent picks up the same session. Jon often checks on his agents through tmux over SSH from his phone. Claude Code's Remote Control mode, which would let you follow a session from the Claude app, isn't available on NEU's Claude seats, so tmux is how you check in from somewhere else.
Port forwarding
The app runs in your workspace, and you want to click through it in the browser on your laptop. Forward two ports with the Coder CLI, on your laptop:
# once: install the Coder CLI (https://coder.com/docs/install) and log in
coder login https://work.ripley.cloud

# each time: forward the app (3000) and the Supabase API (54321)
coder port-forward <your-workspace-name> --tcp 3000,54321
If you connect with SSH instead, ssh -L 3000:localhost:3000 -L 54321:localhost:54321 coder.<your-workspace-name> does the same thing. VS Code Desktop forwards the ports for you.
Leave that running and open http://localhost:3000. Forward both ports: the page loads from 3000, but your browser talks to Supabase directly on 54321 to log in and load data, so with only 3000 forwarded the login page loads and then nothing works. Forwarding to the same port numbers also matters, because the prod build has http://localhost:3000 built into it.
Step 1: Identify
Open your team's user-research.md from User Research & Product Thinking. It lists who your project affects, what they're trying to get done, and the guess your team starred. Pick one flow in your project area that serves one of those jobs, and the roles that use it. A flow that touches your starred guess is the best choice. Then name one concrete bug in that flow: from your ticket hunt, from your team's backlog, or one you find by clicking through it yourself. The agent's analysis is easier to check when you already know one thing it should find.
If nothing in your project area fits, claim a ticket marked XL in the cs4535-first-ticket pool instead, by commenting on it. The ticket names the bug and the flow for you.
Some XL tickets are a group of related issues. Every issue in a group carries the XL label, but the XL ticket is the whole group, not any one issue in it: each issue is too small on its own, and they share code or a root cause, so they're cheaper to fix together. A comment on each issue says why. The groups:
| XL ticket | Issues |
|---|---|
| Self-review due date and status are right for students | #1051, #1006, #527 |
| Instructors can see who has finished their self-review | #1052, #929 |
| An extension grades work the student already pushed | #467 |
| Manually graded assignments show Pending, not 0 | #994, #1057, #1001 |
| A new contributor's clean checkout works: quick start, tests, and type checks | #1004, #991, #1012, #993 |
| Course settings update live without the expensive database watcher | #1026 |
| Survey answers are never lost | #977, #1005, #1013, #1002 |
To claim a group, post it in the Discord thread (see below), then comment on its first issue. You take all of its issues.
Claim it in the activity's Discord thread before you start, whether it's a flow and role ("office hours, the TA's view of the queue") or a pool ticket ("XL: survey answers are never lost, #977"). Read the thread first, and keep an eye on it afterwards. Don't take something someone else has already claimed. Two people on the same issue, or two PRs that change the same screen in different ways, waste both people's work and both reviews. Pick a different flow, role, or ticket instead. The only exception is if the pool runs out, and then we'll say so in the thread. If your plans change, post that you're releasing your claim, so someone else can take it.
Step 2: Engage
Give the agent a prompt in this shape. Fill in the parts in angle brackets.
Analyze
<the flow>in Pawtograder, from the point of view of<roles>. Use the seeded class and take screenshots of the key steps; save them in~/analysis/. We need to improve usability, and fix at least this bug:<the bug>. Consider all the variants of the flow:<e.g. a submission that's assigned to a grader, and one that isn't>.<What makes the flow painful, e.g. "It is very cumbersome to grade 20 students.">Recommend changes, most important first. Don't change any code yet: we'll discuss the ticket scope for a PR first.
For a pool ticket, start the prompt with "Read issue #<N> and reproduce it," and keep the rest.
The example this is based on was: "Analyze our grading interface. Take screenshots of the key steps in it. We need to improve usability, and fix at least this 1 bug: when a submission is assigned to a grader it shows 'assigned to <uid>' instead of the name. Consider all flows: if grading is assigned to the user, or if they don't have grading assigned. It is very cumbersome to grade 20 students. It might be nice to remember at least the tab you were looking at on the last submission. We will discuss the ticket scope for a major PR."
What came back, after about 25 minutes with permissions bypassed, is this report on the grading interface. Open it now. Steps 3 and 4 use it as their example.
Expect yours to take about 25 minutes too. Don't wait for it. Click through the same flow yourself in your browser, as each role, and write down what's slow, confusing, or broken, before you read anything the agent wrote. Keep the list: your reflection compares it with the agent's report.
Step 3: Evaluate
Read the screenshots and the recommendations. For each recommendation, decide:
- Is it right? Check it against the app, not against the agent's description of the app. Agents describe screens they never looked at.
- Did it find your bug? If not, why not?
- What did you find that it missed, and what did it find that you missed?
Ask the agent follow-up questions, and have it take more screenshots if a step is missing.
Then mark each recommendation evidence or guess, the way you marked assumptions in user-research.md. The agent isn't a user. It isn't even one kind of user, the way you are. A recommendation is evidence when you can see the problem in the app: a page that shows a user ID where a name belongs, a dead end, a step that loses your place. It's a guess when it's about what people want, how they feel, or how often something happens: "graders would prefer a keyboard shortcut." Guesses go to your team's user study to be checked, not straight into code.
Example: evaluating the grading interface review
The grading interface report is good material to practice on, because it makes every claim checkable:
- It shows its evidence. Each finding has a screenshot and a
file:line, so you can check the claim instead of trusting it. - It separates what it saw from what it read. One finding is marked "from code only", and a section at the end lists its method and caveats: the seed data, and a test mask it turned off.
- It found more than it was asked to. It confirmed the bug, then pointed out that the one-line fix only helps the person who already knows the answer, because the box only ever shows the viewer their own assignment. Every other staff member sees no assignee at all.
- It leaves the product decisions to a person. It ends with five questions to settle, rather than answering them itself.
A report this careful is still worth checking. Bring up the same flow locally and drive it yourself:
| The report says | How you'd check it locally |
|---|---|
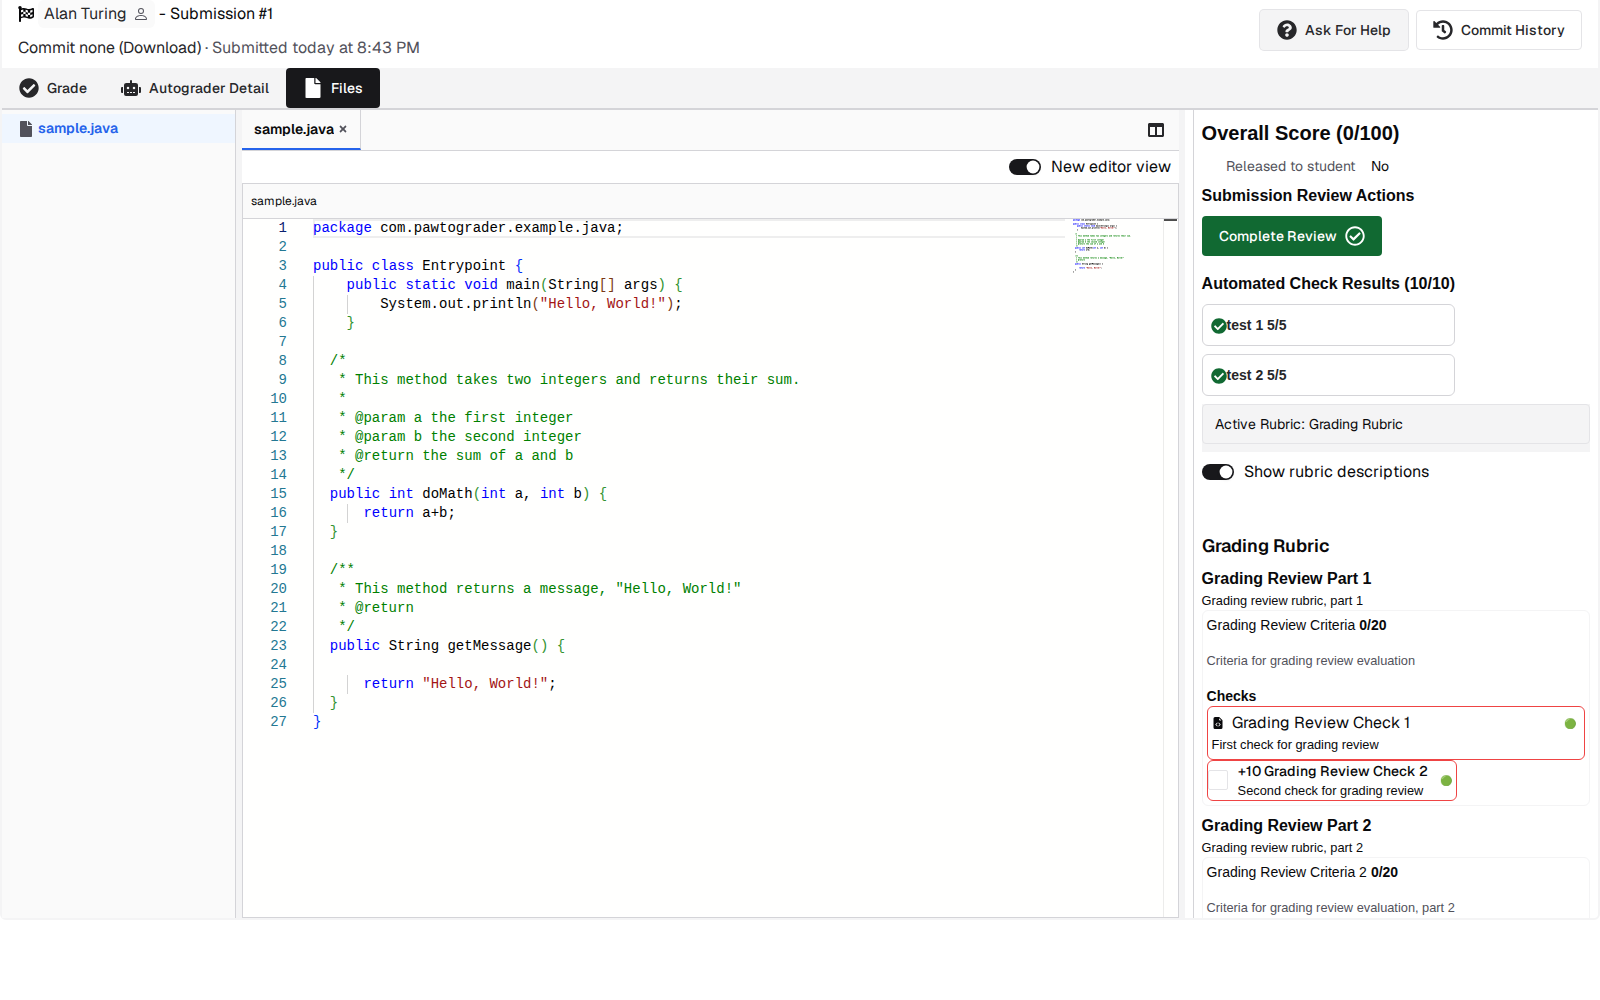
| The Review Task box shows a UUID | Log in as the seeded grader and open an assigned submission. This is evidence you can see in one click |
| Other staff see no assignee at all | Log in as the instructor and as the second grader, and open the same submission |
| The two Complete buttons write different tables | Click each one, then look at review_assignments and submission_reviews in Supabase Studio (port 54323, so forward it too). The claim comes from reading the code, so check what actually changed |
| "Next" follows submission ID, not the table's order | Look at the seed. With six students created in order, ID order and name order may be the same, and then this screenshot can't show the difference. What data would? |
| The rubric starts below the fold | That was measured on a 1600×1000 window. Is it true on your laptop, and on a TA's? |
| A grader can complete someone else's review | Click it as the second grader. Is that a bug or a feature? The agent can't know. (It's a feature: several graders can each be assigned different rubric parts of one submission.) |
| The Survey tab is "the screen the grader actually wants", and 20 students means 20 extra clicks | Mark these as guesses about graders. Ask a TA |
Line references like layout.tsx:2175 | They point to staging at commit 146759be. Check that they still point at the right code |
Also look for what it didn't cover. It never used a keyboard alone or a screen reader. It also never tried a class with 200 submissions instead of six.
For participation, you can stop here and write it up (see Submission).
Step 4: Calibrate
Steps 4 to 6 aren't due this week. Start them when you start your project work or your First Implementation Ticket.
Write up what held up as an issue on pawtograder/platform, with your team's label and the screenshots. For a pool ticket, add it as a comment on that ticket instead. Use the format from From a Finding to a Ticket for each finding:
| What we saw | One specific observation, with a screenshot |
| Who, and how many | For an agent's finding, usually nobody yet. Say so, and mark it a guess |
| What it cost them | Time, errors, a workaround, giving up |
| The change we suggest | |
| How we'd know it worked | The same task, run again after the change |
The agent can draft the issue with gh issue create. Add the screenshots by dragging them into the issue in your browser. We haven't automated that part yet 🙃
This issue is a scoping exercise for your First Implementation Ticket. That ticket has to be XL:
- A pool ticket marked XL counts as it is.
- A ticket from your own project counts if its scope is as large as an XL pool ticket. Agree the scope with Jon by mentioning
@jon-bellon the issue, by Mon Oct 19.
An XL ticket is too big to review as one PR, so scope it into a stacked series of PRs that you can each review line by line, and list them in the issue in the order you'll build them. The First Implementation Ticket rubric already allows "a stacked series with a stated plan." The plan goes in the issue.
Example: calibrating the grading interface review
The report ended with a proposed scope in tiers and five questions. Jon's whole reply was:
Tier 1. Keep in URL. Completing moves you to next automatically. Next follows same as the dropdown menu and the "next" button shown for review assignments. Graders can complete each other reviews (relevant when there are multiple assignments for different rubric parts of one submission).
That's a calibration in five sentences. It picks a scope (Tier 1, with Tier 2 left for later). It answers the open questions in one line each. It overrules the agent's suggestion to remember tabs in the URL and in local storage, choosing the simpler one. Its last answer uses something the agent couldn't have known about how courses assign graders. Your reply should do the same: settle what's yours to settle, in a sentence each.
Tier 1 is XL-sized: about five changes across the toolbar, the sidebar, and navigation. Jon can review it as one PR because Pawtograder is his project. Scoped for someone who can't, it would be a stack of four PRs, each reviewable on its own:
- The assignee's name shown to every staff member, which fixes the bug. It changes both the query and the UI
- The current tab kept in the URL across every link to another submission
- One completion control that moves you to the next submission
- The Survey tab as the default on survey-only assignments
Each piece has to be something you can stand behind. Say which job in your user-research.md it serves, what evidence supports it beyond the agent's opinion, and how you'd know it worked. If a piece rests on a guess about users, your team's study is where to check it, and the demo build from the next step is a prototype you can put in front of them.
Step 5: Tweak
Start a goal for the first PR in your stack. First create a branch from staging named agents/ plus your GitHub username plus a few words naming the change, e.g. agents/jdoe/assignee-name-for-staff. Then:
/goal implement
<the changes you picked>on this branch, with tests, committing as you go. Then leave a prod build running on port 3000 with a seeded class that demonstrates the fix, and post the login email and password for each role in the chat.
When it's done, open the demo through your port forward and click through the flow as each role. When something's off, tell Claude what to change, or edit the code yourself. Repeat until it's right.
Keep it running
A /goal keeps Claude working after each turn until a separate model, the evaluator, judges that the goal is met, judges it impossible, or an error stops it. It can run for hours. The /goal docs cover the details. The commands you need:
| Command | What it does |
|---|---|
/goal <what you want> | Starts working toward it right away |
/goal | Shows the goal, how long it's run, the turn count, the tokens used, and the evaluator's latest reason |
/goal clear | Stops it |
Your workspace stays up for 14 days, but a session in a closed browser tab doesn't. Run Claude inside tmux and it keeps going after you disconnect:
| Command | What it does |
|---|---|
tmux new -s agent | Starts a session named agent |
Ctrl-b then d | Detaches. Claude keeps running |
tmux attach -t agent | Reattaches later, from any terminal |
tmux ls | Lists your sessions |
If the tmux session is gone, for example because the workspace restarted, your conversation isn't. Run claude --resume to pick a past session from a list, or claude --continue to reopen the most recent one. An active /goal comes back with it.
The goal pauses if you reach your Claude usage limit, and it resumes when the limit resets.
Use the usage limit to your advantage. Your Claude seat has a usage limit that resets every five hours. Usage you don't spend before it resets is gone, so the time you're away is free agent time. Before you stop for the day, start a big /goal in tmux, such as the next PR in your stack. It works while you're in class or asleep, and when you come back you'll have a fresh usage limit and, with luck, finished work waiting. Then spend your own time on the part the agent can't do: reviewing what it made. Pick a goal you'll be able to review when you get back, the same rule as everywhere else in this activity.
Step 6: Finalize
Open a draft PR, and keep it a draft until you've reviewed it yourself. Nothing merges to staging while Jon is away, so drafts are fine.
- Run
/code-reviewon your own PR, scoped to the part you can judge. It takes a path, so/code-review high app/course/reviews one directory instead of the whole PR. - Decide which findings are real.
/code-reviewproduces candidate problems. For each one, reproduce it or point to the line that proves it, or else throw it out. - Write the PR description yourself: what changed, why, how you checked it, what the agent got wrong, what you still can't vouch for, and a link to the issue with the rest. #1050's "Needs a human" section is a good model for what you can't vouch for. Add before and after screenshots.
- Bonus: record a walkthrough video of the bug and then the fix, and drag it into the PR description. 🙃 again.
When you review someone else's PR, the same rule applies. /code-review --comment posts findings under your name, so post only the findings you've checked. The code review handout counts a review only if you're ready to answer questions about it at a demo day, whether you wrote it or an agent drafted it.
AI Policy
The course AI policy applies: you're responsible for everything you ship, regardless of who or what wrote it. An agent wrote the code, but the PR has your name on it, so don't take it out of draft until you can explain every line.
Grading
This activity isn't a separate assignment. It counts in two places:
| What counts | Graded by | |
|---|---|---|
| Participation for Oct 7 | Your writeup showing that you tried this with Claude Code, in your Coder workspace or on your own machine, through step 3 (see Submission) | Submitted by Fri Oct 9 |
| Your First Implementation Ticket | The XL ticket you scoped in step 4, built as the stack of PRs you planned, review-ready by Oct 29, then reviewed, merged, deployed, and verified by Nov 4 | The First Implementation Ticket rubric |
Steps 4 to 6 are where that ticket starts, on your own schedule. Nothing is due for them this week, and draft PRs can't merge until Oct 14 anyway.
Submission
By Fri Oct 9, commit these to notes/<github-handle>-agents/ in your Team Workspace repo:
- Your transcript. Run
/exportin Claude Code and save the file. - The agent's artifact: its screenshots and recommendations.
- Your own list from your walkthrough in step 2.
- Your reflection, about a page, in your own words. Under the AI policy, reflection is the one thing you don't use AI for. Answer these:
- Compared with your own walkthrough, did the agent help? Put your list from step 2 next to its report. Did it find things you missed? Did it miss things you found? Or did it mostly write down things you'd noticed but hadn't taken the time to write down?
- Compared with the ticket hunt: is this the same process you used to find and file tickets in September, or a different one? How did it compare: what did the agent make easier, and what did it make harder or skip?
- Which recommendations were evidence and which were guesses?
- What did the agent get wrong, and how did you find out?
- What would you delegate differently next time?
- Your setup: did you use the Coder workspace or your own machine? What got in the way?
Then post in the activity's Discord thread: your flow and role (or pool ticket), the bug you named, and links to your notes, plus your issue and draft PR if you made them.
Dates
| When | What |
|---|---|
| Before Wed Oct 7 | Workspace set up; you can log in to the seeded class from your laptop |
| Wed Oct 7, class time | Steps 1 to 3 |
| Fri Oct 9 | Participation: transcript, artifact, and reflection in notes/, and your post in the thread |
| Wed Oct 14 | staging unfreezes; drafts can come out of draft after your own review |
| Thu Oct 15 to Wed Nov 4 | First Implementation Ticket: pick your XL ticket by Mon Oct 19 (own-project scope agreed with Jon by then), review-ready by Oct 29, merged and verified by Nov 4 |